Janus
September 18, 2026 · View on GitHub


Janus sends each decision to a small model or to a larger one, according to how confident the small model is. It measures where that line sits on your data before it routes anything. Janus ships no default threshold: it measures one.
It measures from either of two inputs:
- a labelled dataset —
--dataset, with a gold label, so the report is about how often each model is right; - a log of decisions already taken —
--log, with a confidence and no gold label, so the report is about how often the logged model agrees with a reference model. There is no ground truth in a log, and Janus refuses to print a word that would suggest one.
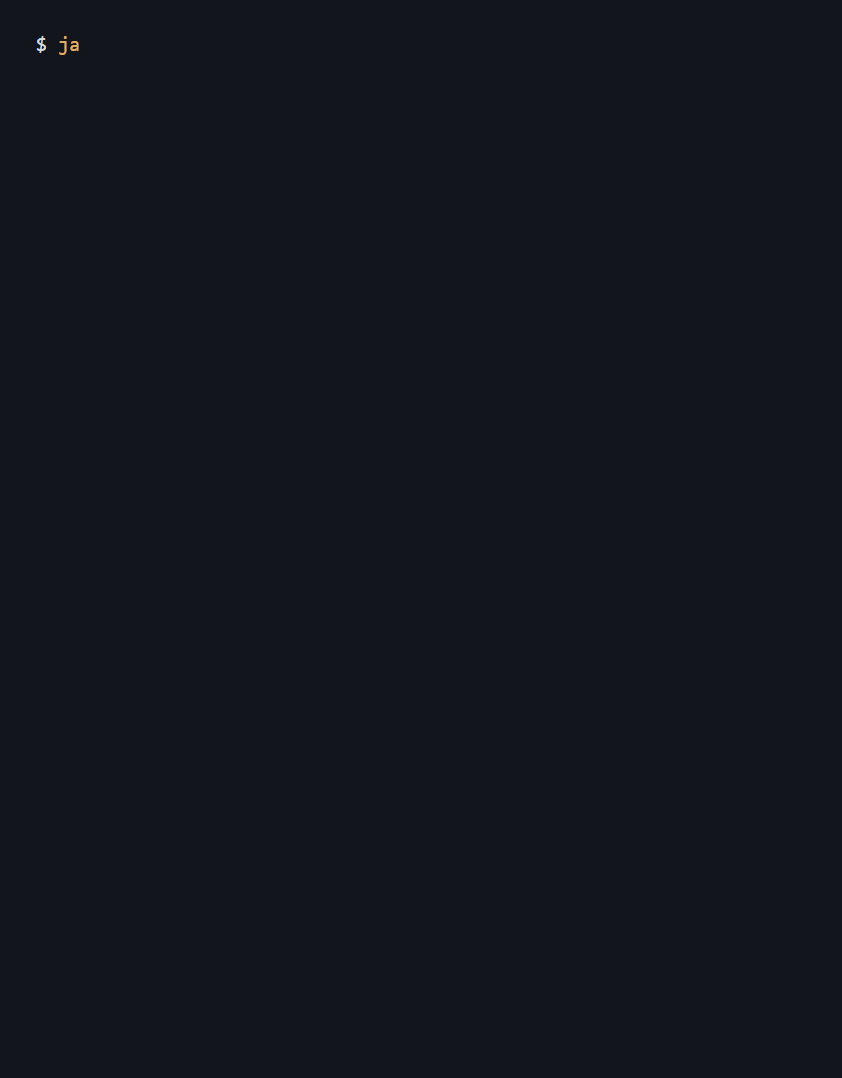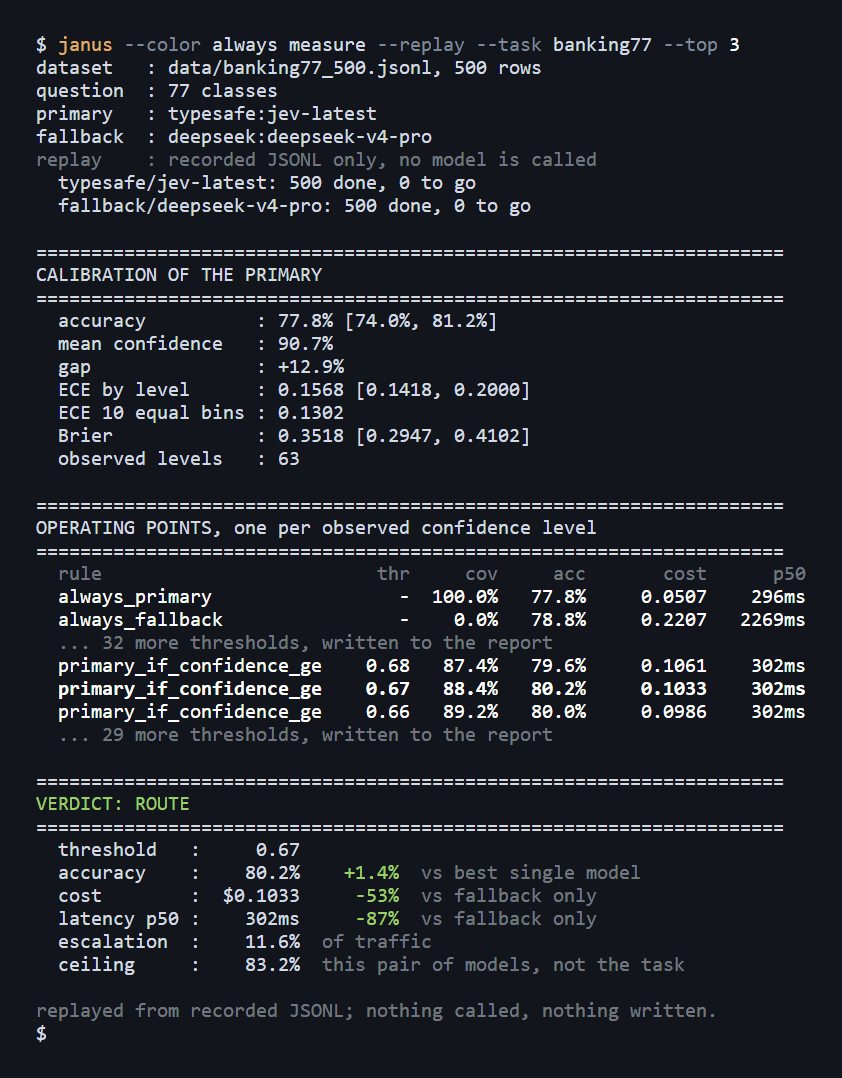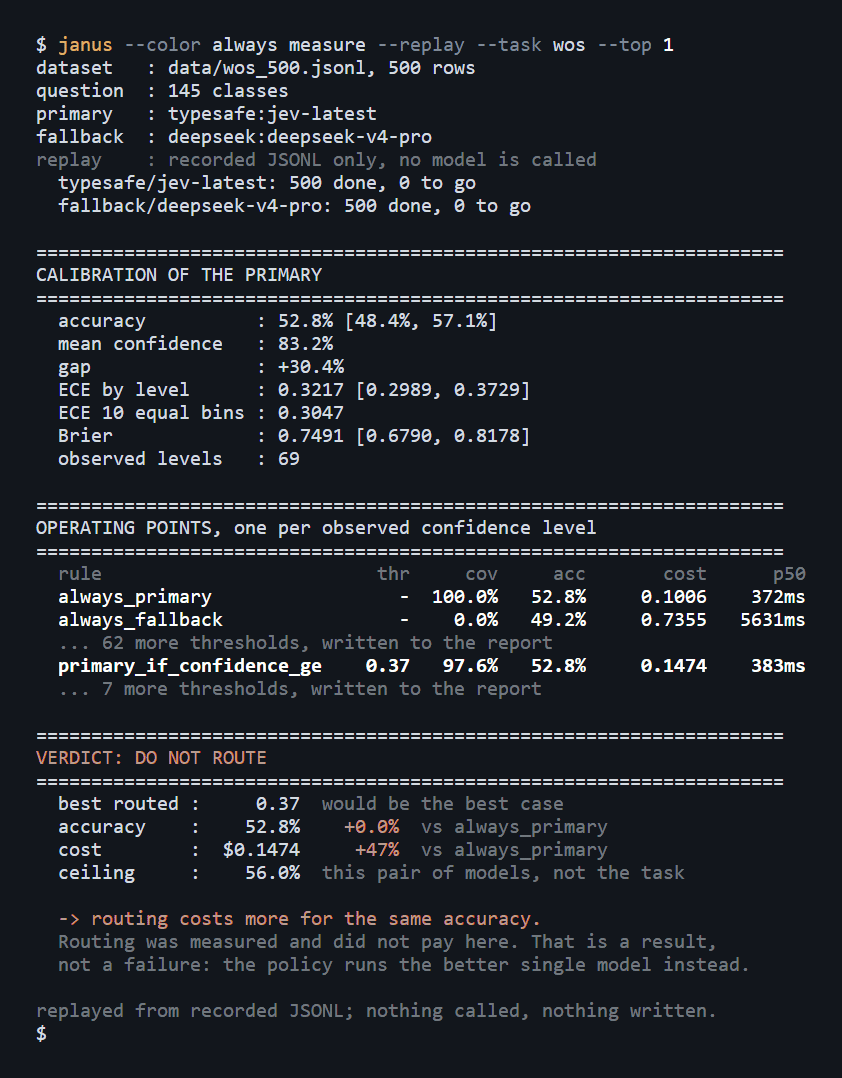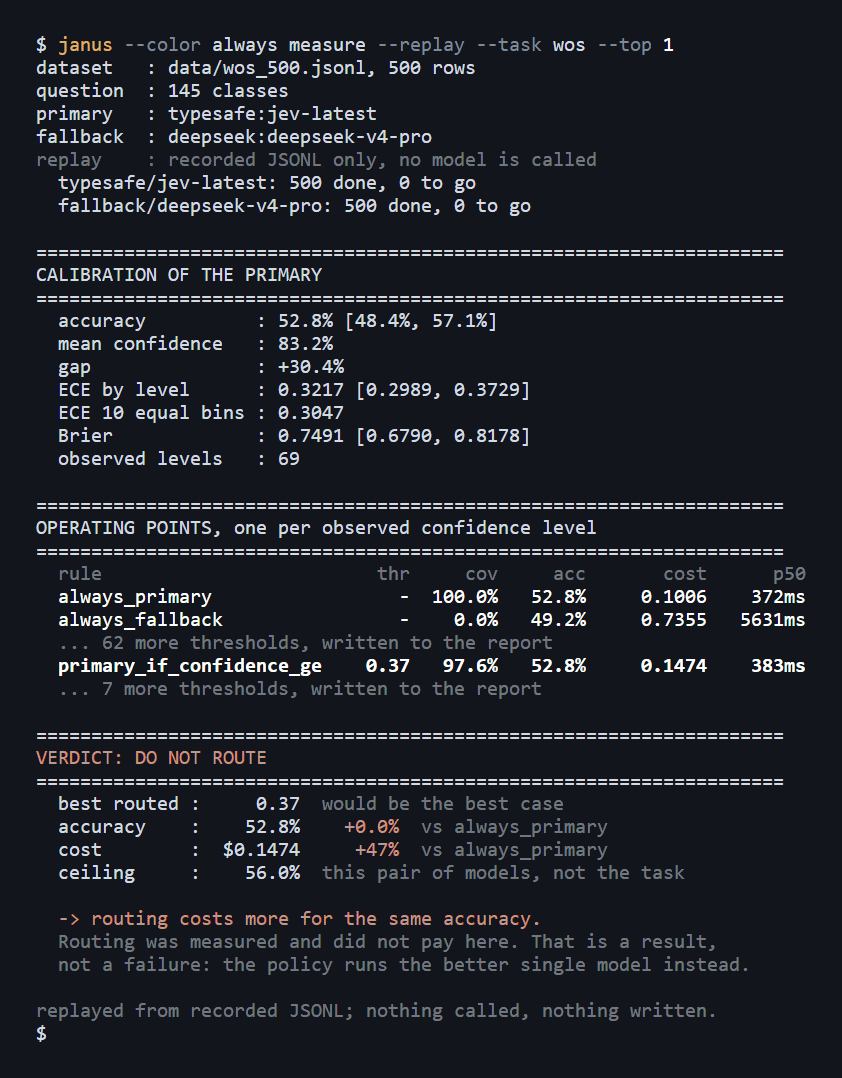
Real output, replayed from the raw JSONL committed in this repository. No model is called.
pip install janus-decide
Quickstart
Five minutes, on your own data. Janus ships no default threshold: it measures one.
1. Install
pip install "janus-decide[typesafe,deepseek]"
The bare package depends only on numpy; each backend is an extra. DeepSeek speaks the
OpenAI protocol, so [deepseek] and [openai] pull the same client.
2. Prepare a labelled JSONL — one object per line, three fields:
{"id": 0, "text": "I lost my card", "gold_label": "lost_or_stolen_card"}
{"id": 1, "text": "when does my card arrive", "gold_label": "card_arrival"}
and a label file naming every class you allow:
{
  "instructions": "Which banking intent does this customer query express?",
  "labels": {
    "lost_or_stolen_card": "The card has been lost or stolen.",
    "card_arrival": "Chasing a card that was already ordered and has not arrived."
  }
}
Start with a few hundred labelled rows; larger samples generally give more stable estimates. Ours were 500.
3. Measure
janus measure \
  --dataset mydata.jsonl --labels mylabels.json \
  --primary typesafe:jev-latest \
  --fallback deepseek:deepseek-v4-pro \
  --out janus.json
Try --sample 20 --seed 1 first: it checks the wiring and the real cost per call
before you spend on the full set. --budget 2.00 stops the run if the projected cost
goes over. An interrupted run resumes by id without re-paying for a completed call.
4. Read the table. This is the real output for the Banking77 data in this repository:
  rule                         thr     cov     acc       cost      p50
  always_primary                 -  100.0%   77.8%     0.0507    296ms
  always_fallback                -    0.0%   78.8%     0.2207   2269ms
  ... 33 more thresholds, written to the report
  primary_if_confidence_ge    0.67   88.4%   80.2%     0.1033    302ms
  ... 30 more thresholds, written to the report

VERDICT: ROUTE
  threshold   :     0.67
  accuracy    :    80.2%    +1.4%  vs best single model
  cost        :  \$0.1033     -53%  vs fallback only
  latency p50 :    302ms     -87%  vs fallback only
  escalation  :    11.6%  of traffic
  ceiling     :    83.2%  this pair of models, not the task
The full sweep is written to the measurement report.
The verdict compares each number against the baseline the decision is actually made against. accuracy is read against the better of the two models alone. cost and latency p50 are read against the fallback, since routing exists to avoid calling it: here that is less than half the money and a median decision that still answers in about 300 ms, against 2.3 seconds. If you are building anything interactive, that last line matters before the other two.
measure can also conclude DO NOT ROUTE, which is what it does on the second
dataset in this repository: no threshold beat the better single model, so the policy
runs that model alone rather than paying for an escalation that buys nothing.
5. Route from Python
from janus import Router, question_from_json, resolve

question = question_from_json("mylabels.json")
router = Router.from_file(
    "janus.json",
    primary=resolve("typesafe:jev-1.13.0"),     # the resolved version, not the alias
    fallback=resolve("deepseek:deepseek-v4-pro"),
)

decision = router.decide(input="I lost my card", question=question)
decision.label       # "lost_or_stolen_card"
decision.source      # "primary" | "fallback"
decision.escalated   # False
decision.cost_usd    # from real tokens; None when the rate is unknown
Pin the resolved version here rather than an alias: an alias moves when a release
ships, and a threshold measured on one version does not transfer to the next. Aliases
are fine in janus measure, which records whatever the API actually answered.
When the models do change under you, janus check says so, and Router raises
instead of quietly applying a threshold measured on something else. janus explain
shows why one input escalated and another did not.
Use it from an agent
An agent skill ships in this repository. With it installed, a coding agent can be asked directly:
Measure my thresholds with Janus.
and will find the decision logs or labelled data already in the project, work out their format and the classes actually used, assemble the question from what the project states, estimate the cost, run the measurement, and read the report back. It will not invent a log, a label, a question or a number: when something needed is missing, it says which and stops.
Claude Code plugin
claude plugin marketplace add FirasSX914/Janus
claude plugin install janus@janus
Invoke it explicitly with /janus:janus-decide.
Other agents via skills.sh
npx skills add FirasSX914/Janus --skill janus-decide
Select your agent when prompted. Installation is project-local by default; add
-g to install globally.
| Skill | Purpose |
|---|---|
| janus-decide | Find the project's decision logs or labelled data, measure the threshold, and report coverage, agreement and cost |
The skill describes the commands and flags of the version it ships with and adds nothing to them. It reads SKILL.md as its instructions; the raw Markdown can be fetched by an agent that installs skills another way.
Why measure at all?
The same pipeline was run on two labelled datasets, 500 examples each, and no routing parameter carried over. The optimal threshold moved from 0.67 to 0.37. The sign of the accuracy gap between the two models reversed. On one dataset routing beat both models on its own; on the other it matched the better one while costing 47% more, so the honest answer there was not to route.
A default threshold would therefore be wrong roughly as often as it was right, which is the whole reason this tool measures instead of assuming.
Full measurement, raw data and limitations: RESEARCH.md.
Research
Two datasets, 500 examples each, protocol frozen before any result, raw JSONL and figures committed. The headline is that nothing measured on the first dataset predicted the second.
- RESEARCH.md — results, calibration, ECE and Brier, agreement between the models, limitations, related work.
- docs/METHOD.md — the protocol, what was fixed before each run, and the constraints measured on the APIs themselves.
- experiments/ — the scripts that produced it.
Reference
Every flag and file format, in docs/REFERENCE.md: janus measure and its two sources, janus check, janus explain, the Python API, the providers, the file formats and the repository layout.
License
MIT — see LICENSE.
Banking77 is distributed under CC BY 4.0; see data/README.md for
provenance and citation.