Learning through Creation: A Hash-Free Framework for On-the-Fly Category Discovery 🔥
March 13, 2026 · View on GitHub
-- [arXiv link] --
Overview
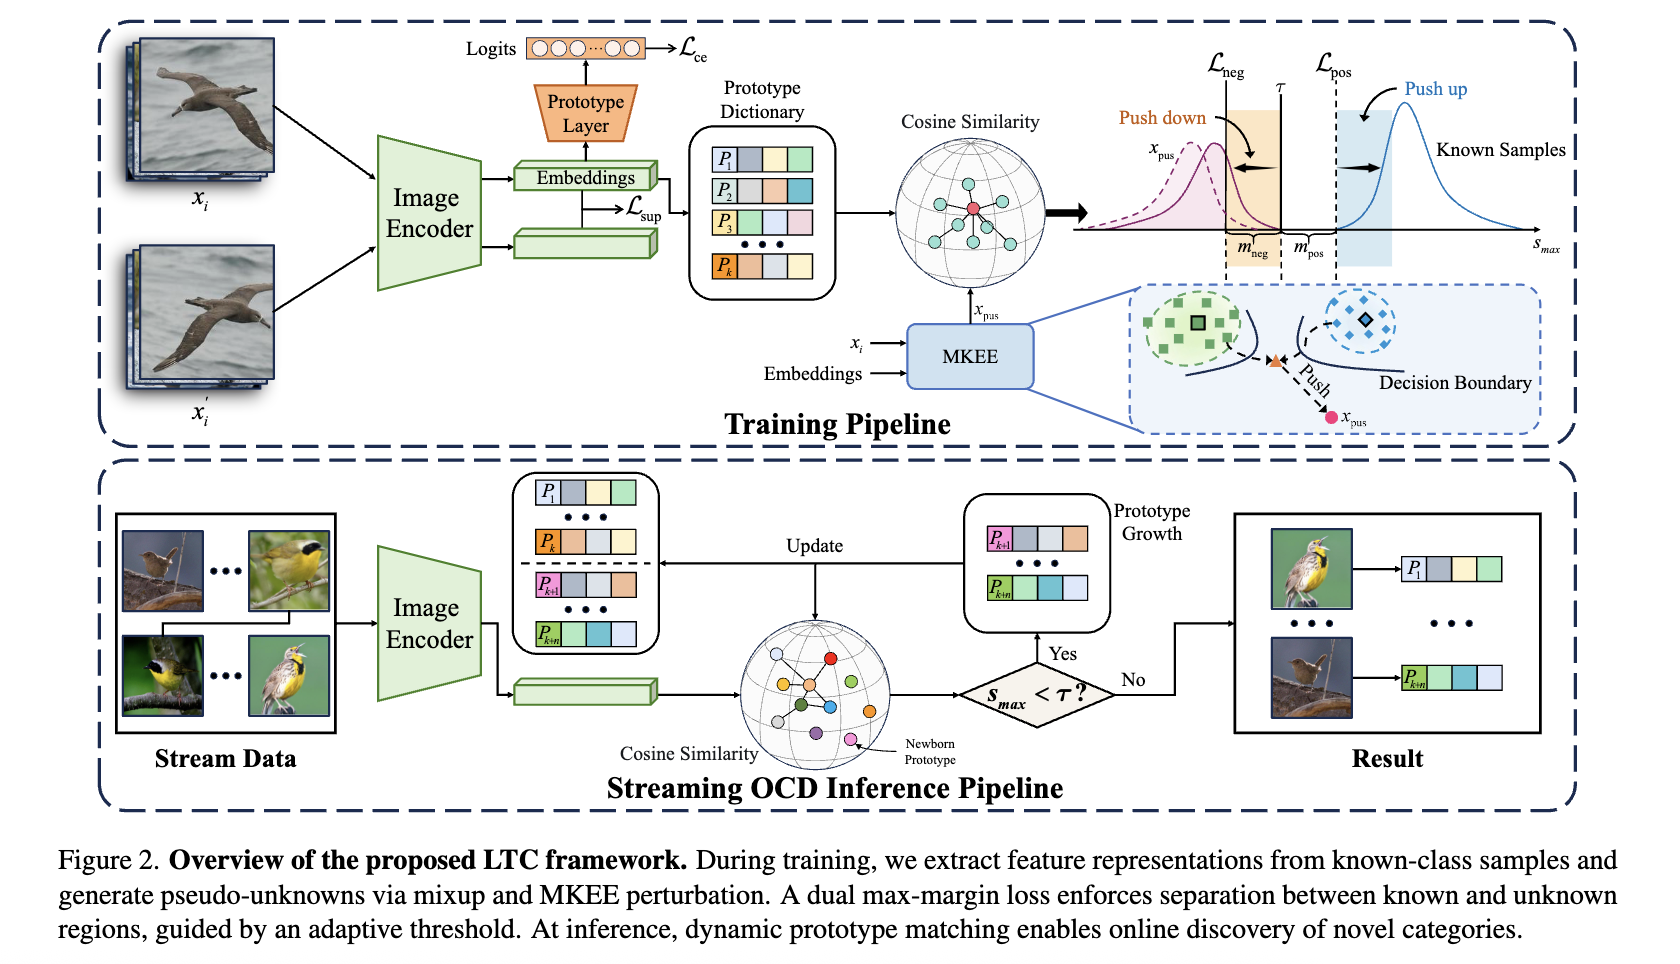
This repository contains the implementation accompanying Learning through Creation (LTC) for on-the-fly category discovery built on CLIP ViT-B/16 visual features. The method combines:
- A prototype-based classifier head (cosine similarity)
- Contrastive learning with two augmented views
- A max-margin objective with an adaptive threshold (initialized by
tau_train) - MKEE: entropy–kernel guided pseudo-unknown generation for stronger open-set training
Environment Setup
Install dependencies
- Recommended: Python 3.10 (Linux/macOS). Windows is not officially tested.
Install all pinned dependencies (reference environment):
pip install -r requirements.txt
PyTorch installation notes (CUDA)
requirements.txt pins torch/torchvision versions for reproducibility, but GPU builds depend on your CUDA toolchain. If you need CUDA, install PyTorch following the official selector, and then install the rest:
pip install -U pip
# (1) install torch/torchvision with your CUDA build (see official selector)
# (2) install the remaining packages
pip install -r requirements.txt --no-deps
pip install numpy pandas scipy tqdm pillow timm ftfy regex clip-by-openai
Path Configuration
All dataset root paths and the (optional) pretrain checkpoint path are defined in [config.py]
cub_rootcar_root(Stanford Cars)food_101_rootoxford_pet_rootinaturalist_rootcifar_rootimagenet100m_root(ImageNet-100 merged, ImageFolder format)pretrain_path(currently not required by the CLIP-based default pipeline, but kept for compatibility)
Example
Edit config.py to your local filesystem paths, e.g.:
cub_root = "/data/datasets"
car_root = "/data/datasets/stanford_cars"
food_101_root = "/data/datasets"
oxford_pet_root = "/data/datasets"
inaturalist_root = "/data/datasets"
cifar_root = "/data/datasets"
imagenet100m_root = "/data/datasets/ImageNet-100-merged"
pretrain_path = "/data/pretrain/dino_vitbase16_pretrain.pth"
Reproduction workflow (recommended)
tau_train is the initial value of the adaptive threshold τ used by the max-margin objective and later refined online via a quantile target + EMA. To reproduce, please use the setting in our CVPR paper, then:
-
Configure dataset roots in
config.py -
Install the dataset,then run each dataset at a time, e.g. CIFAR-10:
bash scripts/train_ci10.sh
- For a full reproduction sweep, run:
bash scripts/train_ci10.sh
bash scripts/train_ci100.sh
bash scripts/train_pets.sh
bash scripts/train_cub.sh
bash scripts/train_food.sh
bash scripts/train_scars.sh
bash scripts/train_im.sh
Expected outputs
Each run creates the following under --output_dir:
train-logs/: training logs (file + console)checkpoints/last.pth: the latest checkpoint (overwritten each epoch)tf-logs/: reserved directory (not required for core execution)