Laya-MLX
September 19, 2026 · View on GitHub
Open-weight typed decisions, running natively on Apple Silicon.
13.4 ms median end-to-end for a short English typed decision. 7.4 ms with the multilingual checkpoint. 0 output tokens. Local MLX inference, with no PyTorch, Transformers runtime, or cloud API.
中文 · Benchmarks · Snake demo · Hugging Face weights
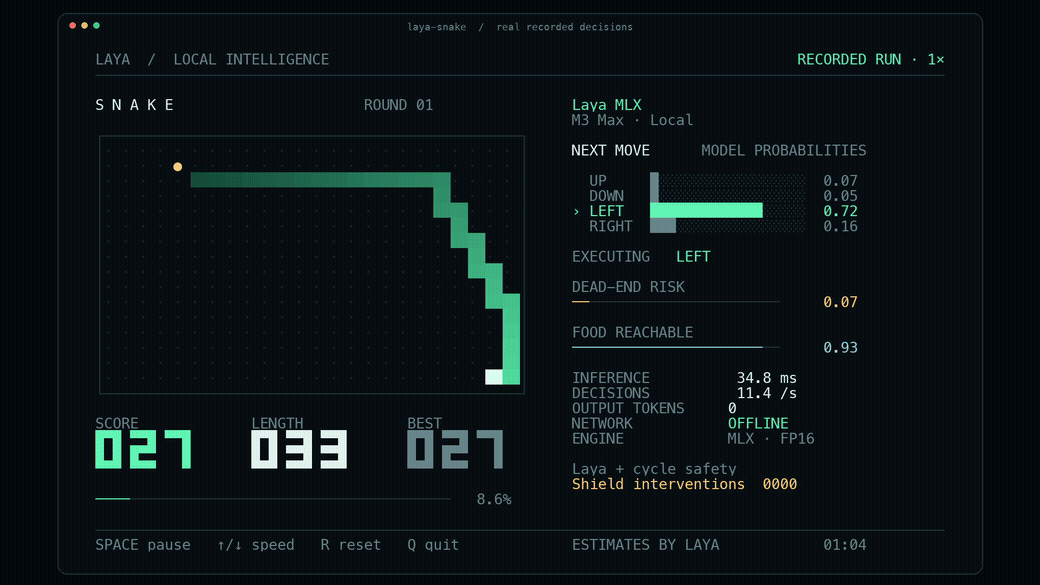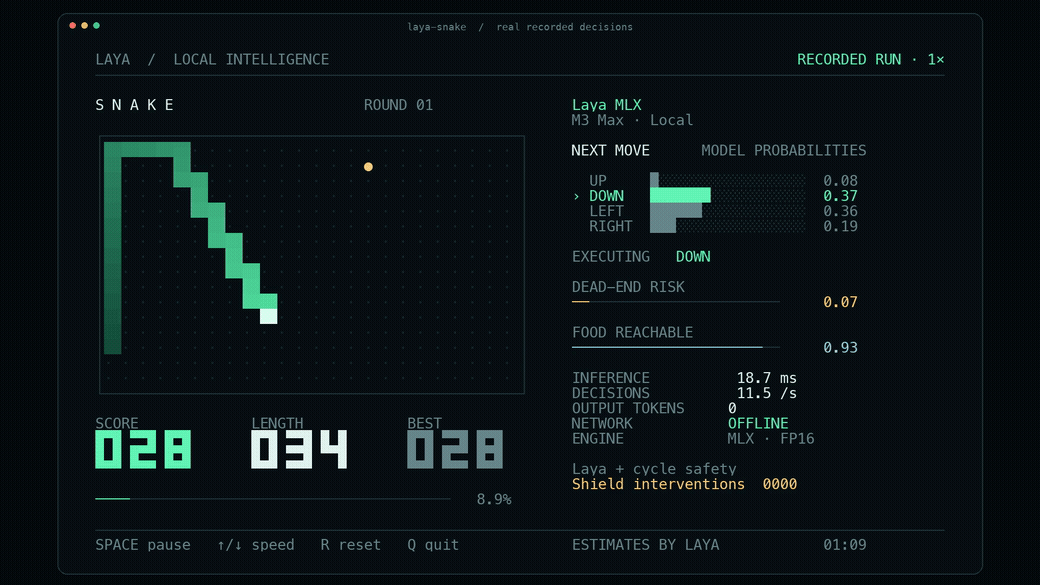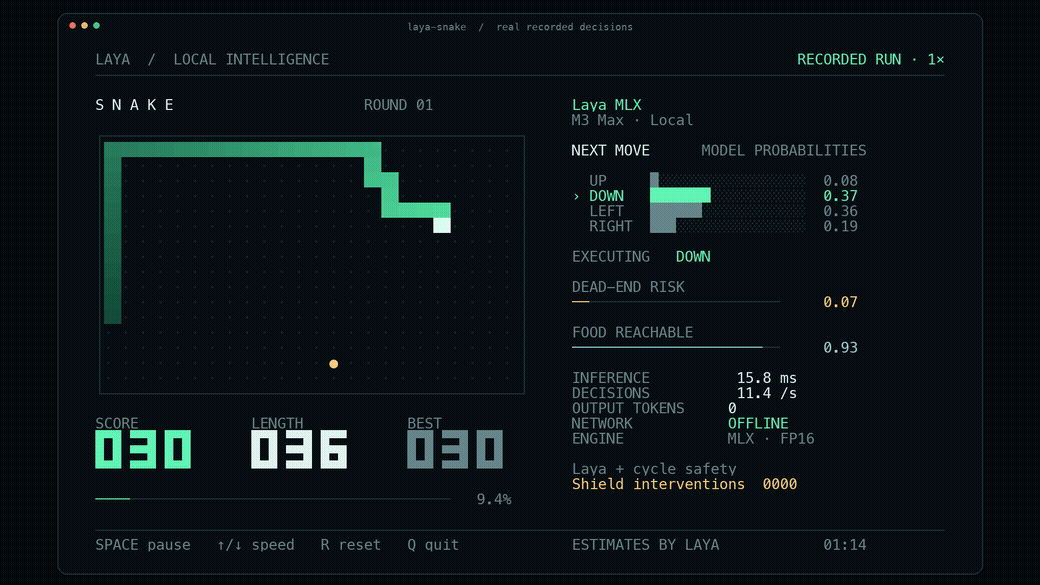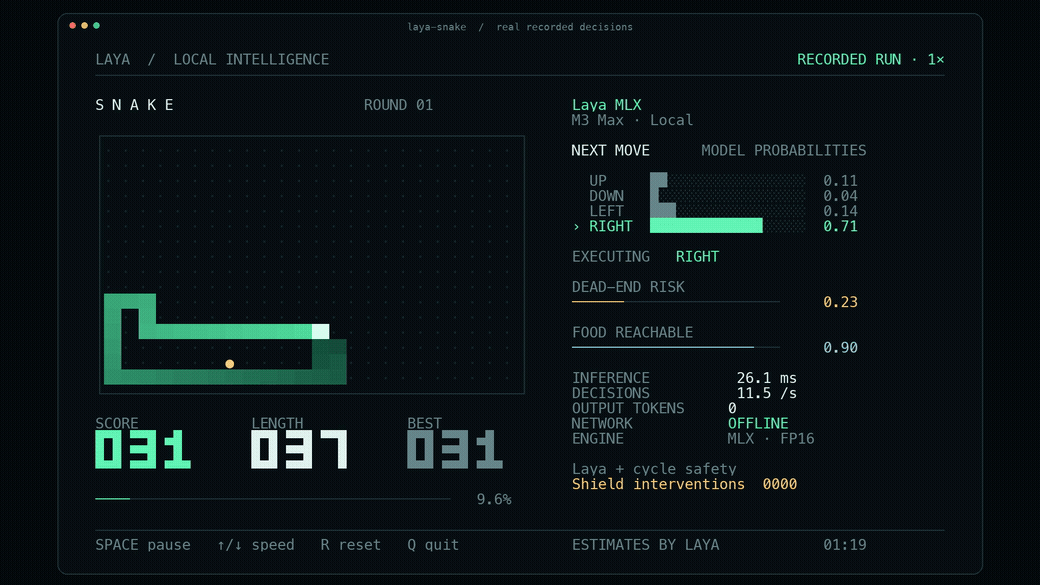
The GIF is an original-speed render of a real local Snake run. Every move calls Laya; the visible cycle safety layer can correct unsafe proposals. The latency figures above are the separate one-question API benchmark, not the frame time of the three-question Snake loop. Watch the 30-second MP4 · Snake speed and stability.
Quick start
pip install laya-mlx
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx")
result = agent.predict(
    "I was billed twice. Please refund the duplicate.",
    {
        "department": {
            "type": "choice",
            "instructions": "Who should handle this?",
            "criteria": ["billing", "technical", "sales"],
        }
    },
)
print(result["answers"]["department"])
Apple Silicon, Python 3.11+, macOS 14+. First load downloads the checkpoint; later inference is fully local. The measured environment is macOS 27.2, Python 3.12.13 and MLX 0.32.2. That MLX release supplies macOS 14, 15 and 26 wheels; the local installer selected the 26 wheel. Older supported macOS versions were not tested on this machine.
Run the terminal demo:
pip install 'laya-mlx[demo]'
hf download aac6fef/laya-multilingual-mlx
laya-snake
Download once before the offline demo. Use a terminal at least 104 × 35 cells. Space pauses, ↑/↓ changes speed, R resets and Q quits. laya-snake --max-speed makes a fresh decision for every move without pacing. Recording, controls and exact metric meanings.
laya-snake --optimize --max-speed enables the tested compilation and prefix-reuse path: 75.40 moves/s across 2,400 moves, zero deaths and 2 visible safety interventions in the paired M3 Max test. This was about 6.5% faster than its same-run eager control. Gameplay, performance and correctness evidence.
Performance on M3 Max
| FP16, end-to-end | Laya 421M | Multilingual 322M |
|---|---|---|
| One short question, P50 | 13.42 ms | 7.39 ms |
| One short question, P95 | 13.92 ms | 7.79 ms |
| 50-question throughput | 146.8 q/s | 395.0 q/s |
| Peak MLX allocation, one short question | 943.6 MiB | 687.6 MiB |
M3 Max, 40 GPU cores, 128 GiB memory. Timing includes prompt preparation, tokenization, tensors, synchronized inference, calibration and result formatting; model loading is excluded. The 50-question measurement uses batch_size=64; the API defaults to 16. Different lengths, question counts and runtime conditions change latency. Full method and every timing sample.
Port fidelity: all three checkpoints matched the upstream selected answer on 63/63 validation questions in both FP32 and FP16 — 378/378 comparisons. Each configuration also passed 100 repeated finite, deterministic calls with zero measured active-memory growth. This measures fidelity on those fixtures, not accuracy on every possible question. Probability errors and validation.
Why typed decisions?
Software often needs a choice, a rubric score or a probability. Laya answers those constrained questions in a bidirectional forward pass, without token-by-token decoding or generated JSON.
state + typed question → bidirectional encoder → decision heads → probabilities
choice: probabilities over named options.score: probabilities over ordered rubric levels and their expected score.noul: P(true) for a proposition.
Question rows are batched independently. Their bidirectional encoder representations depend on both state and question; this runtime does not claim to encode the state once and reuse its hidden states across arbitrary questions.
The encoder, decision Transformer, scoring head and action head all run in MLX. Tokenization uses Hugging Face's Rust tokenizer. The original pretrained weights, question formatting, calibration and output schema are retained. This is an independent MLX port, not an official Convai Innovations release.
Supported checkpoints
| Model | Encoder | Parameters | Context limit | Purpose |
|---|---|---|---|---|
convaiinnovations/laya | ModernBERT-large | 421M | 512 | English |
convaiinnovations/laya-multilingual | mmBERT-base | 322M | 1,024 | Multilingual input |
convaiinnovations/laya-typed-decisions | ModernBERT-large | 421M | 1,024 | Upstream typed-decisions workflows |
Context includes instructions, options and state. All three use the original weights, prompt formatting, temperature calibration, and output schema. This repository provides inference and conversion; RLCD training and fine-tuning remain in the upstream project. It is an independent port, not an official Convai Innovations release.
Pre-converted FP16 checkpoints are published on Hugging Face:
Load these directly with laya.load("aac6fef/laya-mlx"), or use the original checkpoint IDs above. Each published checkpoint includes its model card, validation results, provenance, license and file checksums. All 36 published files passed strict remote checksum verification; pinned revisions and weight hashes are recorded in hub-publication.json.
Development install
gh repo clone mizorewww/laya-mlx
cd laya-mlx
uv sync --extra demo
uv run --extra demo laya-snake
Or install the latest GitHub revision with pip install 'git+https://github.com/mizorewww/laya-mlx.git'. Model weights are downloaded separately and are excluded from Git.
Python API
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx", dtype="float16")
result = agent.predict(
    "I was billed twice. Please refund the duplicate today.",
    {
        "department": {
            "type": "choice",
            "instructions": "Which team should handle this request?",
            "criteria": {
                "billing": "invoices, payments, refunds",
                "technical": "bugs and outages",
                "sales": "new purchases",
            },
        },
        "urgency": {
            "type": "score",
            "instructions": "How urgent is this request?",
            "criteria": ["not urgent", "soon", "critical"],
        },
        "refund": {
            "type": "noul",
            "instructions": "Does the customer ask for money back?",
        },
    },
)
print(result["answers"])
system_one is an alias for predict. States can be text, JSON dictionaries, or conversation lists. choice accepts a dictionary or a list of unique labels; score returns the expected zero-based rubric level; noul returns P(true). Results retain upstream's four-decimal rounding, action.act_probability, and token usage fields.
The default precision is FP16. Use dtype="float32" for closer numerical agreement. Probabilities can differ slightly across precisions even when the selected label agrees; see the measured errors in BENCHMARKS.md. BF16 can be requested but is not part of the published validation matrix.
batch_size=16 caps the number of questions per forward pass; larger requests are processed in chunks. Increase it when memory allows. device="gpu" or device="cpu" selects a device explicitly; otherwise MLX's default device is used.
For repeated workloads, opt into compile=True, pad_to_multiple=16 and cache_prompts=True when loading an Agent. The prefix cache is bounded to 128 questions and shares CPU state tokenization, while every question still gets its own encoder computation. Compilation has a first-use cost and shape specialization; padding may make some workloads slower. All three options default to disabled. Measured Snake ablation and usage.
agent = laya.load("./models/laya", dtype="float32", batch_size=32)
# Select one checkpoint inside upstream's bundled repository:
multi = laya.load("convaiinnovations/laya", subfolder="multilingual")
# Pin a Hub revision for reproducibility:
agent = laya.load(
    "convaiinnovations/laya",
    revision="c5d78730f3493e4fe16d61507ef4b78eef7318cf",
)
Loading validates every parameter name and shape. Unsupported encoders and non-default RoPE scaling fail explicitly. ModernBERT's global/local attention pattern, inclusive sliding-window boundary, distinct local/global RoPE bases, and first-layer normalization behavior are preserved.
Language routing and presets
from laya_mlx import Router, triage_questions

router = Router(dtype="float16", max_loaded=2)
result = router.predict({"message": "发票被重复扣款,请退款。"}, triage_questions())
print(result["routing"])  # multilingual

# Choose the specialized checkpoint explicitly:
result = router.predict(state, questions, task="typed_decisions")
The router, language heuristics, email helpers and application presets are adapted from upstream. Router(preload=True) keeps all three checkpoints resident; attach, preload, unload, explicit lang=, and explicit model= are supported. Typed-decisions workflow detection stays opt-in. The port preserves model limitations: English checkpoints are not substitutes for the multilingual checkpoint, and confidence does not guarantee accuracy.
Command line
uv run laya-mlx predict \
  --model aac6fef/laya-mlx \
  --state-file examples/state.json \
  --questions examples/questions.json

uv run laya-mlx predict \
  --model aac6fef/laya-multilingual-mlx \
  --state '发票被重复扣款,请退款。' \
  --questions examples/questions.json
Export an MLX checkpoint
uv run laya-mlx convert \
  --model convaiinnovations/laya \
  --dtype float16 \
  --output models/laya-mlx-fp16

uv run laya-mlx predict \
  --model models/laya-mlx-fp16 \
  --state-file examples/state.json \
  --questions examples/questions.json
The export contains model.safetensors, encoder and agent configurations, tokenizer files and mlx_config.json. Existing output directories are never overwritten. This is a parameter-name/dtype conversion, not quantization or retraining. The source checkpoints already store FP16 weights; choosing FP32 increases arithmetic precision, not the precision of the source weights.
Tests and benchmarks
uv sync --extra dev --extra reference --extra benchmark --extra demo
source .venv/bin/activate
gh repo clone NandhaKishorM/laya .upstream
git -C .upstream checkout 6a5819129eb220570792e417e49723d697efd76f
pytest -q
python -m benchmarks.download
python -m benchmarks.validate --repeats 100
python -m benchmarks.run --iterations 50 --warmup 5
python -m benchmarks.accuracy --per-class 64
python -m benchmarks.report
Run GPU measurements sequentially. Unit tests use small random models and include direct comparisons with Transformers and the pinned upstream decision head. Real checkpoint validation tests tokenization, logits, calibrated probabilities, repeated outputs and active memory growth. The benchmark runs each backend/checkpoint in a fresh process and stores every timing sample in benchmarks/results. The full report explains the timing boundaries and precision differences.
GitHub Actions runs small-model CPU tests on a macOS arm64 runner. Full checkpoint GPU benchmarks are measured locally and are not part of hosted CI.
Performance research
The performance investigations include both mathematical analysis and independent local experiments:
- Initial performance research: implementation bottlenecks, MLX kernel dispatch, and a controlled experiment plan.
- Mathematical investigation of a further 10× speedup: arithmetic budgets, conditional bandwidth bounds, real weight spectra, exact reuse, and smaller-model designs.
- Engineering investigation: measured compilation, quantization, final-head selection, custom Metal kernels, and representative matrix multiplications.
experiments/ contains the research scripts and their raw measurements. The published runtime's performance and validation results are in BENCHMARKS.md; each experimental variant has its own timing and correctness results.
The current investigation does not support a further universal 10× speedup with the same checkpoints. Selected cases show approximately 1.03–1.08× paired median speedups; the engineering report gives the uncertainty intervals, quantization fidelity results, and custom Metal kernel measurements.
To prepare model cards and verified exports for publication, install the reference extras and run:
python -m scripts.prepare_hub --account YOUR_HF_USERNAME
hf upload YOUR_HF_USERNAME/laya-mlx models/hub/laya-mlx . --exclude '.cache/*'
The preparation script checks every exported tensor against its original FP16 source. Upload the other two prepared folders in the same way, then use hf cache verify REPO_ID --local-dir EXPORT_PATH to check the remote files.
Attribution and license
Apache-2.0; see LICENSE and NOTICE. Laya and its pretrained weights are by Convai Innovations and upstream contributors. Prompt construction, output formatting, language routing, email utilities and presets are adapted from NandhaKishorM/laya at commit 6a5819129eb220570792e417e49723d697efd76f. The neural architecture is reimplemented in MLX following Laya and Hugging Face ModernBERT.