README.md
June 1, 2026 · View on GitHub
MixerMDM: Learnable Composition of Human Motion Diffusion Models

🔎 About
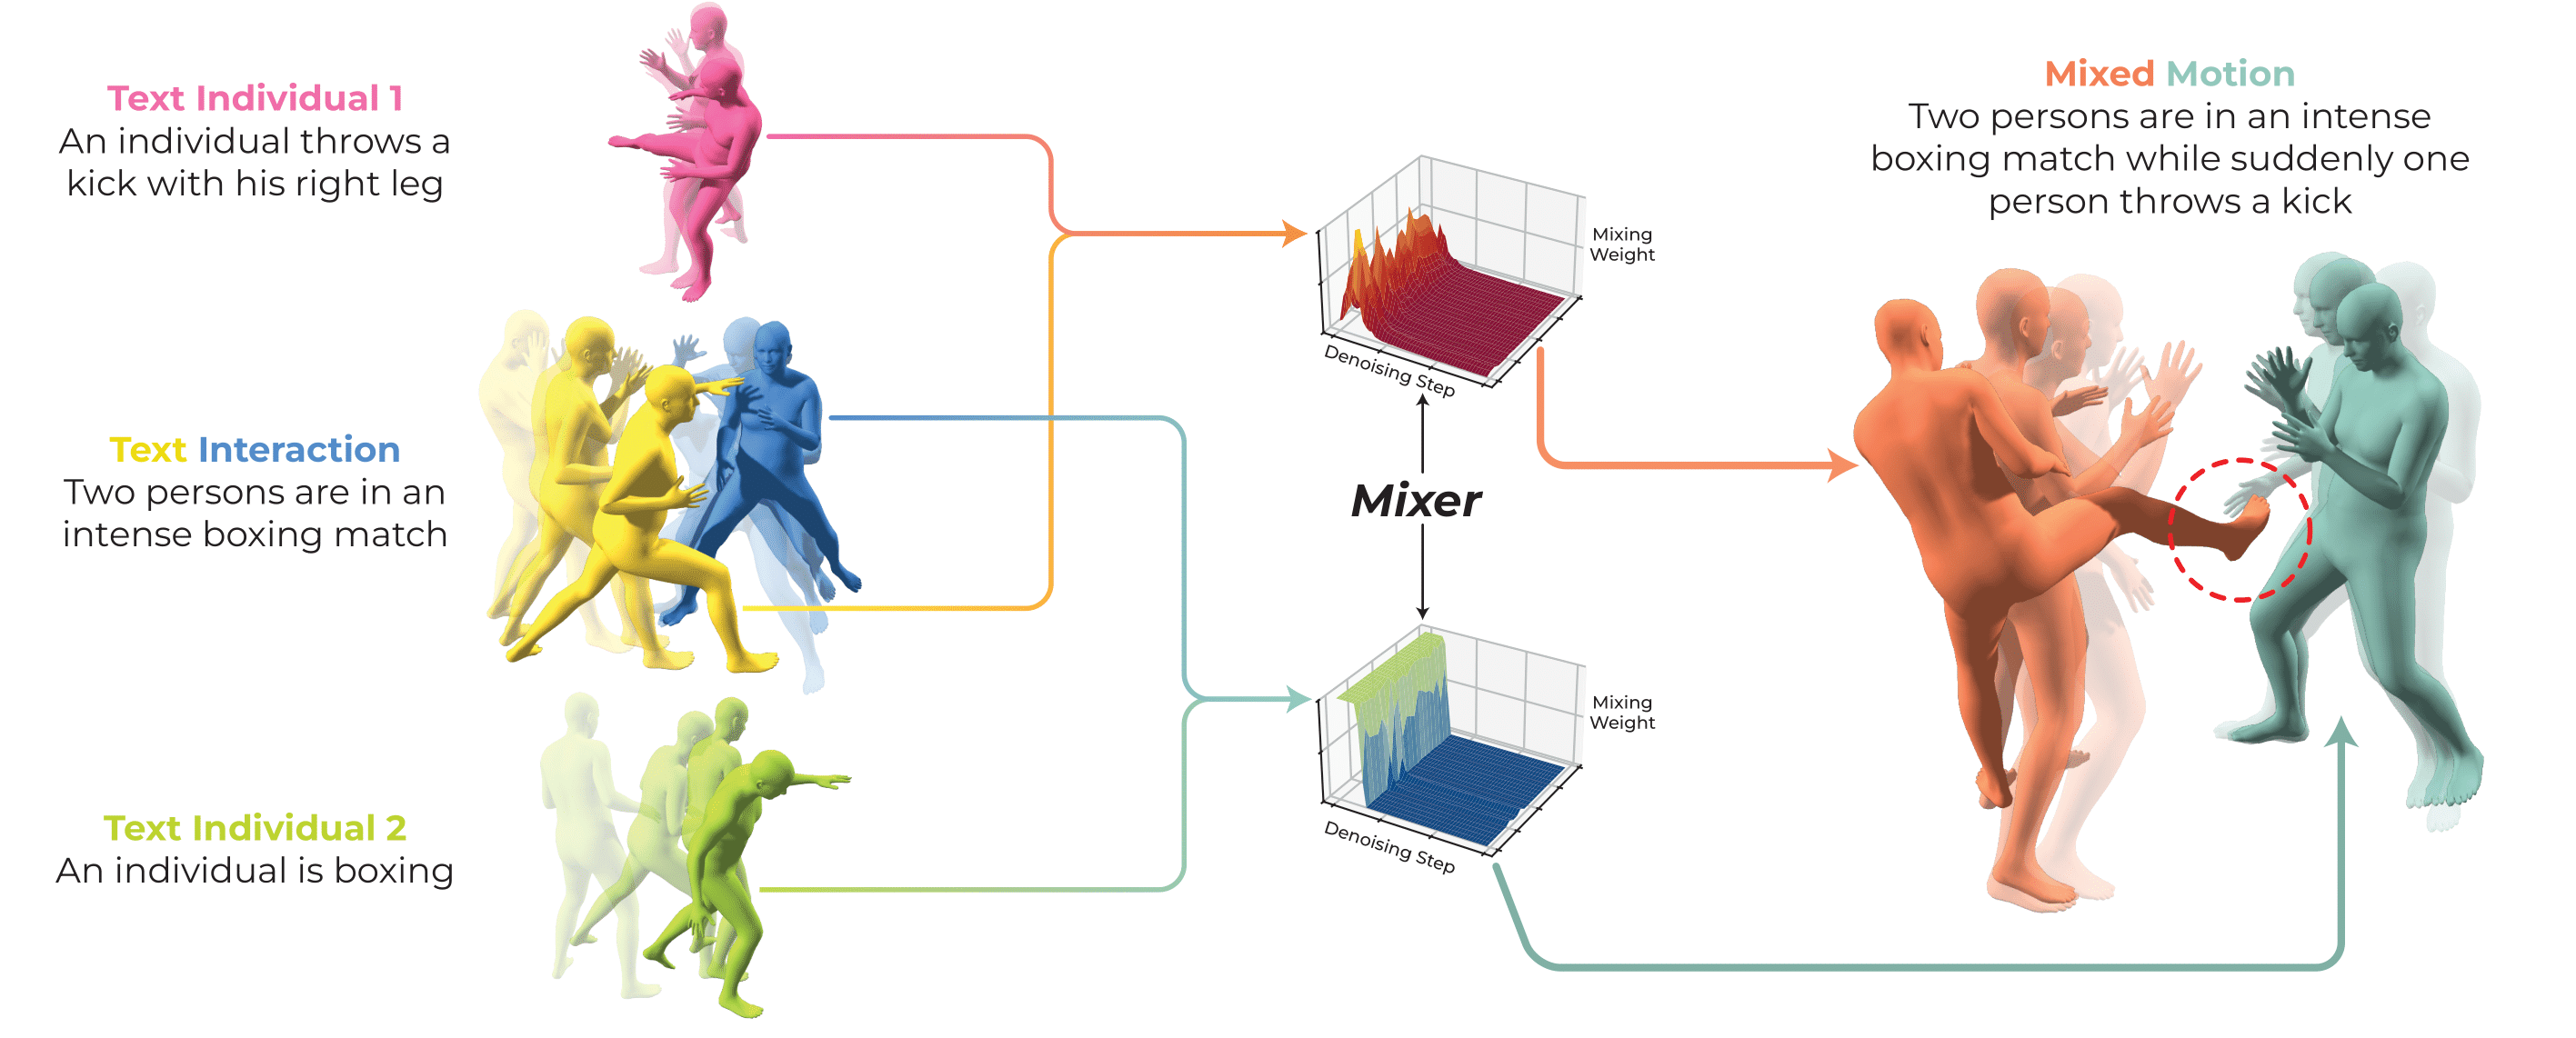
Generating human motion guided by conditions such as textual descriptions is challenging due to the need for datasets with pairs of high-quality motion and their corresponding conditions. The difficulty increases when aiming for finer control in the generation. To that end, prior works have proposed to combine several motion diffusion models pre-trained on datasets with different types of conditions, thus allowing control with multiple conditions. However, the proposed merging strategies overlook that the optimal way to combine the generation processes might depend on the particularities of each pre-trained generative model and also the specific textual descriptions. In this context, we introduce MixerMDM, the first learnable model composition technique for combining pre-trained text-conditioned human motion diffusion models. Unlike previous approaches, MixerMDM provides a dynamic mixing strategy that is trained in an adversarial fashion to learn to combine the denoising process of each model depending on the set of conditions driving the generation. By using MixerMDM to combine single- and multi-person motion diffusion models, we achieve fine-grained control on the dynamics of every person individually, and also on the overall interaction. Furthermore, we propose a new evaluation technique that, for the first time in this task, measures the interaction and individual quality by computing the alignment between the mixed generated motions and their conditions as well as the capabilities of MixerMDM to adapt the mixing throughout the denoising process depending on the motions to mix.
📌 News
- Code and model weights are now available!
- Our paper is available on arXiv
- MixerMDM is accepted at CVPR 2025!
📝 TODO List
- Release code
- Release model weights
- Release visualization code.
💻 Usage
🛠️ Installation
- Clone the repo
git clone https://github.com/pabloruizponce/MixerMDM.git
- Install the requirements
- Install conda environment
conda env create -f environment.yaml - Activate the conda environment
conda activate MixerMDM
- Install conda environment
🕹️ Inference
Download the model weights from here and place them in the checkpoints folder.
  python src/scripts/infer/mixermdm.py \
      --model configs/models/MixerMDM.yaml \
      --infer configs/infer.yaml \
      --out results \
      --device 0 \
      --text_interaction "Interaction textual description" \
      --text_individual1 "Individual textual description" \
      --text_individual2 "Individual textual description" \
      --name "output_name" \
Note
More information about the parameters can be found using the --help flag.
📚 Citation
If you find our work helpful, please cite:
@inproceedings{ruiz2025mixermdm,
  title={Mixermdm: Learnable composition of human motion diffusion models},
  author={Ruiz-Ponce, Pablo and Barquero, German and Palmero, Cristina and Escalera, Sergio and Garc{\'\i}a-Rodr{\'\i}guez, Jos{\'e}},
  booktitle={Proceedings of the Computer Vision and Pattern Recognition Conference},
  pages={12380--12390},
  year={2025}
}