README.md
September 24, 2026 · View on GitHub

The one memory your coding agents share, built from the history already on your disk.
Your agent is about to re-debug something you fixed in March — in a different agent. deja indexes the sessions Claude Code, Codex, Cursor and every other agent on this machine already wrote to disk, and hands the right one back in whichever agent asks.
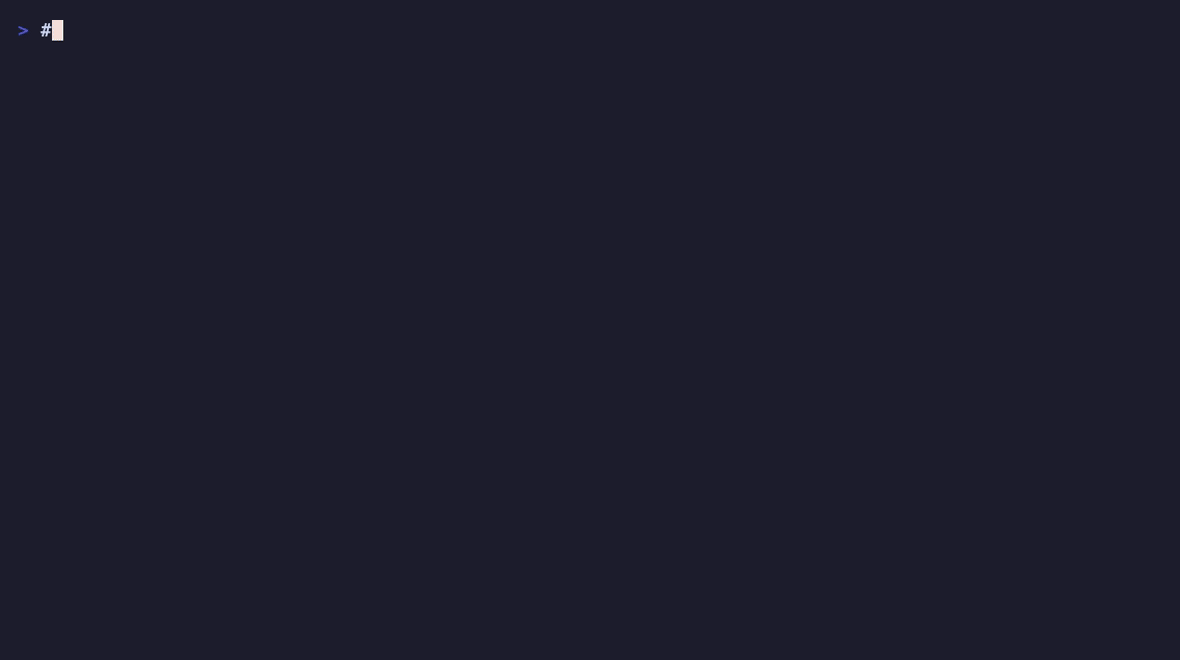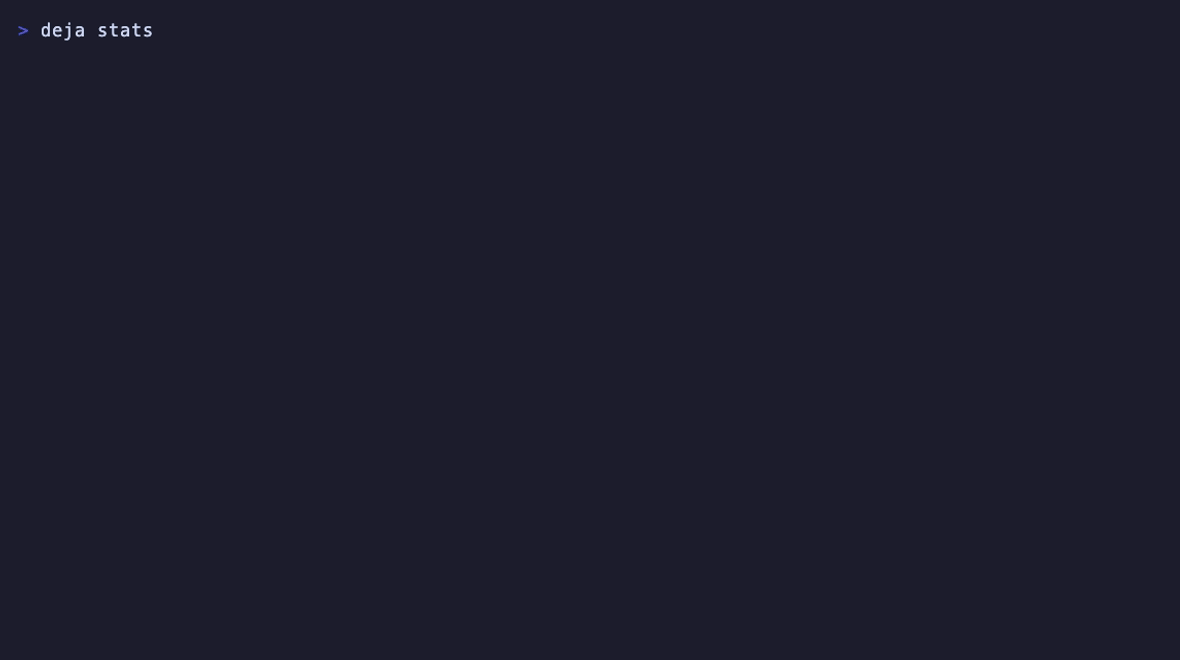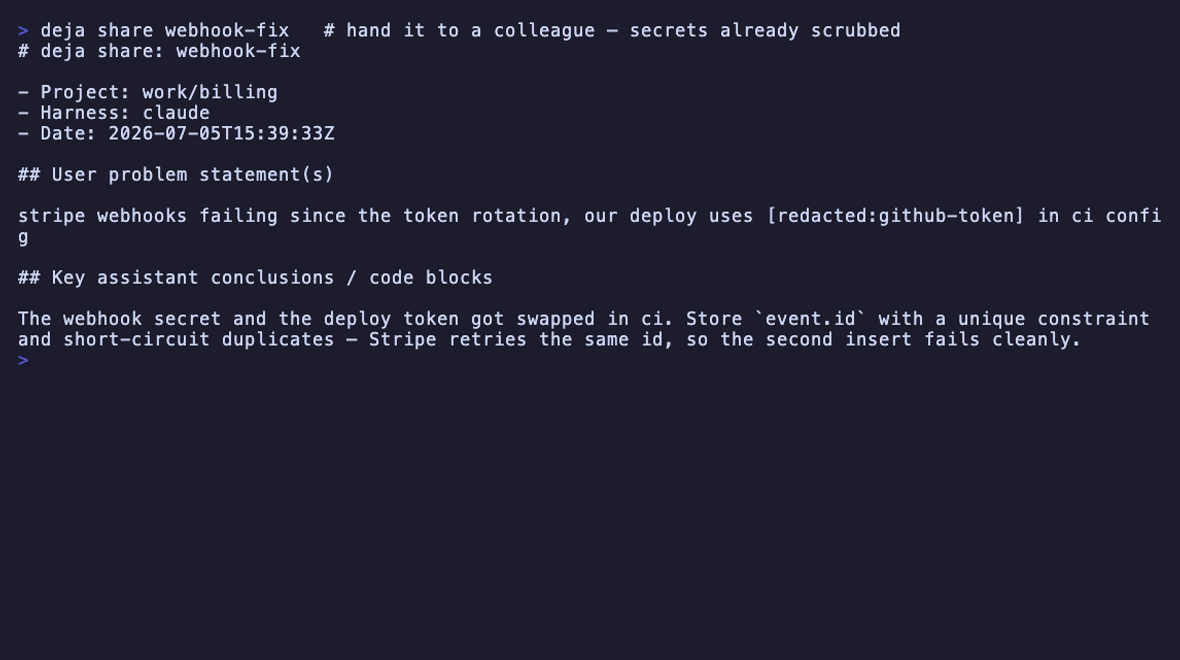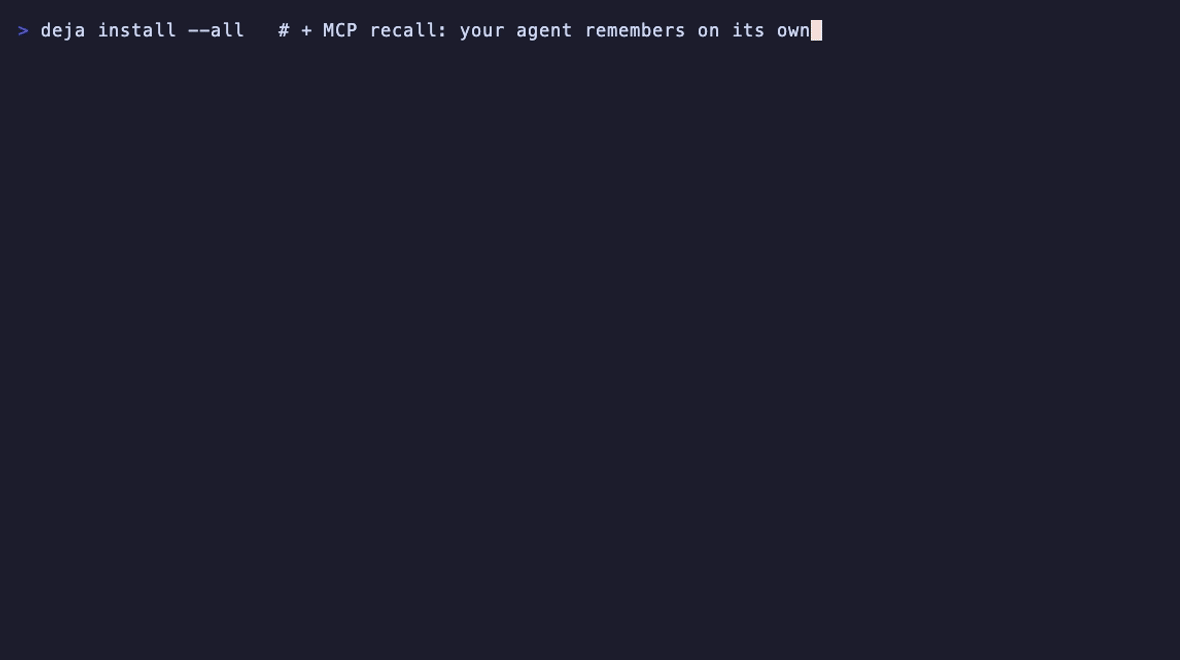
Nobody searched anything — the agent called deja itself. Two genuine runs, a real model and a real tool call, against a synthetic corpus: nobody's history is published.
deja starts full: the history 34 agents already wrote, searchable while it indexes, with no model and no capture step.
And nobody has to ask for it: recall arrives at session start, on every prompt, before a file is edited or a command runs, and after one fails. Keys and tokens are stripped as the index is built; the security model says what that catches and what it cannot.
58% fewer tokens on a task this machine had already solved · 88.1% hit@1 on LongMemEval-S (470-question cleaned set) · 70.5% retrieval hit@1 on LoCoMo · millisecond lookups over gigabytes of history
Eleven runs an arm: 53,558 tokens against 126,222 with nothing wired, and 71% off on a later run of the same stand ·
what it costs to finish one task ·
both retrieval harnesses ship in this repo and run on the public datasets in minutes ·
check the numbers yourself



Docs · Benchmarks · How it compares · Building it into your tool
Found it useful? Star deja-vu on GitHub.
Install
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index, and it is useful. The second command wires MCP recall into every agent it finds, turns on session-start recall where the agent supports it, and builds the first index so the next session does not pay for it.
Start a new agent session and ask it something you worked on months ago:
have we dealt with jwt refresh rotation before? check your memory
It does not have to be asked, either — with auto-recall the agent already knows what you solved in that project when the session opens.
Other ways to install, and what to do if you want less than all of it
brew install deja-vu, go install github.com/vshulcz/deja-vu/cmd/deja@latest,
or npx @vshulcz/deja-vu "query" to try it without installing anything. Desktop apps that
take MCP servers as bundles can open the .mcpb from the
latest release; it carries the binary.
Claude Code, Codex, Cursor, Qwen, OpenClaw and Copilot can take the same plugin bundle from their own marketplaces instead:
claude plugin marketplace add vshulcz/deja-vu && claude plugin install deja-vu@deja-vu
On Windows the install script exits with unsupported OS — it is a shell script. Use
Scoop instead, from the main bucket every Scoop install already has:
scoop install deja-vu
Or take deja-vu_<version>_windows_amd64.zip from the
latest release and put deja.exe on
your PATH, e.g. in %USERPROFILE%\.local\bin.
The binary alone is a complete install for searching: index, search, show, ctx, blame,
--json and redaction need nothing else. deja install is what wires MCP into your agents
and turns on session-start recall — worth having, and optional. On a binary-only setup
deja doctor reports every MCP target as not-wired, which is that setup working as
intended. deja warmup also leaves a skill at ~/.agents/skills/deja-search/SKILL.md
that teaches an agent the CLI contract — deja search --json, ctx, blame, how to read
tier and total — so it knows history is searchable without MCP. The copy in the repo is
skills/deja-search/SKILL.md.
deja install --all is --auto without the session-start recall: agents answer from memory
when they decide to call it, rather than starting each session with it. The
agent setup guide covers what each
harness supports, aider's read-only context file, and the Windows cmd /c deja mcp wrapper.
What gets written into each agent's own guidance file
Install also writes user-level guidance for the harnesses it detects: Claude Code, Codex, opencode, Gemini CLI, Antigravity, Qwen, Kimi Code, pi, Senpi, Copilot, VS Code Copilot Chat, Cursor, Goose, OpenClaw, Hermes, Roo Code, omp, Amp, prime-agent, DeepSeek Harness, Continue, Crush and Zed each get it in their own guidance file (or under the configured XDG_CONFIG_HOME). Re-run rewrites deja's skill or marked block without changing surrounding user content. Use deja install --all --no-guidance to opt out; Grok Build gets the shared skill in ~/.agents/skills, which is what it reads; the ~/.grok/GROK.md written beside it is for the unrelated community CLI that shares that directory. Cursor has no user-level instructions file, so it gets the shared skill in ~/.agents/skills — one of the four places Cursor reads skills from — read only when something looks relevant rather than every session.
What you get
Solve it in Codex. Claude remembers. Thirty-four coding agents write every conversation to local files, and deja turns those files into one memory layer all of them read.
| Retroactive search | deja "connection pool exhausted" over gigabytes, including everything from before you installed deja. Natural-language questions fall back to a relevance tier. Time is a hint, not a filter. |
| Cross-agent recall | The MCP deja tool in recall mode answers "we fixed this three weeks ago" in whichever agent asks, whoever solved it originally. |
| It survives compaction | Measured over 43 compactions: the summary keeps 77% of the decisions and 0.2% of the commands you ran. deja hands back the other 99.8% — and on Claude Code and Codex it captures the task, the files and the commands as the compaction starts, then returns them once in the next session. |
| Recall at the point of action | Before an agent edits a file or runs a command, deja names that file's prior decision, that command's working invocation, or the program this machine does not have. When a command fails, a PostToolUse hook answers with what followed that same error here before — the pair an agent never thinks to ask for. |
| It indexes the work, not just the talk | The files each turn opened, the commands that ran with their exit status, and the exact spans an edit replaced. That is the part every summary throws away. |
Four more: rejected decisions, staleness, sync and handoff, redaction
| It knows what held | deja promote <id> --state rejected --note "why" marks a decision you reverted. Every later hit for that session shows it was tried and rejected, with the reason. Nothing is deleted, and --state accepted takes the mark back. |
| It says when the ground moved | A hit reports 4 files this session touched have changed since, and says nothing when it cannot tell. It never claims anything is unchanged. |
| Sync and handoff | deja sync ssh laptop moves memory between machines, append-only, no cloud in the middle. deja handoff --to codex packages the live context so you can continue in another agent. |
| Redaction | Keys, tokens, JWTs and private key blocks are stripped at index time, so the cache is safe to keep. |
Your own work, wrapped
deja stats --card draws it in the terminal; give it a filename and it writes an
SVG for a profile README. To post it anywhere else, turn it into a
PNG — that page converts it in your own
browser.

The full feature reference lives in the docs.
Privacy
Indexing and search are local. The network is used only by deja update, deja sync ssh,
the version check in deja doctor, and deja embed against an endpoint you set.
Credentials are redacted at index time: AWS keys, api_key= and token= assignments,
bearer tokens and raw JWTs, PEM private key blocks, provider tokens, scheme://user:pass@host
URLs, high-entropy values for shapes no pattern knows, and a password stated in prose —
"the admin password is …", where there is no delimiter for the other rules to find. The
value becomes [redacted:<kind>] and the surrounding text stays searchable. deja share and
deja sync export re-apply redaction on the way out.
The source transcripts are not redacted: agents write command output there verbatim, so a
cat .env or a pasted connection string stays in plaintext. deja secrets lists which
sessions carry one and of what kind, from the markers redaction left; it never prints a
value. One machine held 84 in 42 sessions (credentials in transcripts).
deja secrets --scrub rewrites the transcripts that still hold one, putting the same
[redacted:<kind>] marker where the value was and keeping the original beside the file. It
touches only the kinds the report names, refuses a session an agent is in, and says how many
findings it could not reach: a store with no per-session file cannot be rewritten at all.
deja forget removes sessions from a rebuilt index and writes tombstones, so a later
deja index cannot restore them from the source history. --unforget lifts a tombstone.
Project exclusions are one pattern per line in ~/.config/deja/exclude; a line prefixed
harness: names a store instead — harness:opencode — and deja neither walks it nor asks
for the tool that would read it.
The security model documents data flows, redaction limits, trust assumptions and release verification.
CLI
$ deja "jwt refresh token"
[claude] api        · Jul 8 · 8f31c0a9 — 2 matches
  login started failing after refresh token rotation; jwt kid mismatch in tests
  fixed by reloading jwks cache after rotateKey and adding a clock-skew test
[codex]  web        · Jul 1 · b77d91e2 — 1 match
  refresh token cookie needed SameSite=Lax in local callback flow
Ask your history
| Command | What it does |
|---|---|
deja <query> | Search every history. Multi-word is AND and quoted phrases require contiguous text; a query with no exact match then tries word forms and close spellings, which is where a substring reaches its word (code finds opencode). |
deja | With an index and a terminal: today's sessions, recalls served, a question you asked in more than one session, and a wall your agents keep hitting. |
deja wip | What the last session in this directory was doing: the task, what it settled, the files in flight, the last command and whether it failed — derived from the transcript, not from a note someone remembered to write. |
deja blame <path>[:line] | Which sessions discussed a file, what was decided, and why. With a line: the commit that last changed it, and the session that wrote that line or the text the commit replaced. --attribution prints the line answer alone, as JSON with --json, and --git-note records it in refs/notes/deja. |
deja files <topic> | The other direction: which files the work on a subject actually touched. |
deja how <tool> | How this machine actually runs a thing, with the real flags, from what agents ran before. |
deja fix <error> | What this machine ran after that same error before, when the error did not come back. |
deja friction | Errors that hit three or more separate sessions, with the harnesses named. |
Using what it finds, and moving it between machines
Use what it finds
| Command | What it does |
|---|---|
deja ctx <query> | Markdown digest of the best match, ready to pipe into a prompt. |
deja resume <id> | Reopen a found session in its native harness. |
deja restore <path> | Hand back a span an agent replaced, from the old_string its edit recorded. Never writes over the original. |
deja promote <id> | Distill a session into a curated note with provenance, tags and a lifecycle state. Notes outrank raw transcripts. |
deja share <id> | A sanitized session digest for a colleague, with secrets already scrubbed. |
Move it and check it
| Command | What it does |
|---|---|
deja sync export/import/ssh | Move memory between machines. Watermarked, append-only, idempotent. |
deja view | Your whole memory as one local HTML file. No server, and the file never leaves the machine. |
deja stats | Your agent work, wrapped. --card draws it in the terminal, --card <file>.svg writes one for a profile, --html a browsable timeline. |
deja secrets [--scrub] | Which sessions' source transcripts carry credentials, and what kind. Never prints a value. --scrub rewrites the ones it can, original kept beside the file. |
deja doctor [--deep] | Self-diagnosis, and with --deep, proof of the index against the sources. |
deja mcp | The stdio MCP server, which is what deja install wires in. |
Full reference: commands and JSON output.
MCP tools
The server exposes one tool, deja, with a mode. deja install wires it in, so
this is only needed to configure an agent by hand. The six older tool names
(recall, recall_context, blame, fix, how, remember) still answer for
anything already wired to them.
One tool rather than seven is a cost, not a style choice. A wired-in MCP server ships its tool definitions with every request, so you pay for them each turn whether the agent calls anything or not: 477 tokens here, against 8,283 for the largest of the eight servers measured in day zero. deja's own number was 828 until the schema was cut to one tool with modes.
Arguments and return shapes
| Tool | Arguments | Returns |
|---|---|---|
deja | mode, q, harness?, project?, limit? | Depends on the mode, below. |
q carries whatever the mode asks about. The per-mode names below are still
accepted; they are no longer declared, because the schema is read every turn
whether or not the tool is called.
| Mode | q is | Also reads | Returns |
|---|---|---|---|
recall | the question, or an exact error string, name or flag | harness?, limit?, offset? | Dense matching snippets, capped at 4KB. |
context | the same as recall | harness? | Markdown digest of the best-matching session. |
blame | a file path | harness?, project?, since?, limit?, all? | Sessions that discussed a file. |
fix | the failing output, verbatim | project?, limit? | What this machine ran, or changed, after that same error before. |
how | the tool or target, e.g. go test | project?, limit? | The real invocation, from what agents ran here. |
orient | nothing — it asks about the project | project?, limit? | The commands past sessions ran here and the files they worked in. |
remember | one durable fact or decision | project?, tags? | Stores a durable decision for later recall. |
Supported harnesses
With auto-recall installed, Claude Code and Codex hand deja the transcript as a
compaction starts, and it keeps what the summary is about to drop: the task, the
conclusions, the files, the commands with what each one did, and what was left
open. The next hook for the same session and workspace gives it back once, inside
a 4 KB budget, with a line saying whether the repository moved since. deja stats
counts the tool calls before the first edit after a compaction, which is the
number this is measured against. See automatic compaction
recovery for what is read, what is stored and where the
limits are.
aider · Amp · Antigravity · Claude Code · Cline · Codex CLI · Copilot CLI · VS Code Copilot Chat · Cursor · DeepSeek Harness · Gemini CLI · Goose · Grok Build · Hermes · Kimi Code · omp (Oh My Pi) · OpenClaw · opencode · Continue · Crush · pi · prime-agent (PrimeIntellect) · Qwen Code · Cherry Studio · Senpi · gajae-code · Kimchi Coding · Command Code · ZCode · Kiro · Kilo Code · Roo Code · Zed · CodeWhale.
What each one supports
| Harness | MCP recall | Auto-recall | Skill | Command | Resume | Handoff | Needs |
|---|---|---|---|---|---|---|---|
| aider | ⚠ | ✅ | ✕ | ⚠ | ✕ | ✅ | deja aider |
| Amp | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Antigravity | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Claude Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Cline | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Codex CLI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Copilot CLI | ✅ | ✕ | ✅ | ✅ | ✅ | ✅ | — |
| VS Code Copilot Chat | ✅ | ✕ | ✅ | ✅ | ✕ | paste | — |
| Cursor | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 (IDE chats) |
| DeepSeek Harness | ✅ | ✅ | ✅ | ✅ | ✕ | paste | zstd |
| Gemini CLI | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Goose | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | deja goose |
| Grok Build | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 (grok-dev store) |
| Hermes | ✅ | ✅ | ✅ | ✅ | ✅ | paste | sqlite3 |
| Kimi Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| omp (Oh My Pi) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| OpenClaw | ✅ | ✅ | ✅ | ✅ | ✅ | paste | — |
| opencode | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 |
| Continue | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | — |
| Crush | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | sqlite3 |
| pi | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| prime-agent (PrimeIntellect) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Qwen Code | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | — |
| Cherry Studio | ✅ | ✕ | ✅ | ✕ | ✕ | paste | import the server once in Settings -> MCP; enable the skill for the agent |
| Senpi | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | none |
| gajae-code | ✅ | ✅ | ✅ | ✅ | ✅ | paste | none |
| Kimchi Coding | ✅ | ⚠ | ⚠ | ⚠ | ✅ | paste | none |
| Command Code | ✅ | ✅ | ✅ | ✅ | ? | paste | none |
| ZCode | ✅ | ✅ | ? | ? | ? | paste | sqlite3 for the CLI database |
| Kiro | ✅ | — | ✕ | ? | ✅ | paste | none |
| Kilo Code | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | sqlite3 for the CLI store |
| Roo Code | ✅ | ⚠ | ✅ | ✅ | ✅ | paste | roo CLI (editor tasks reopen in the editor) |
| Zed | ✅ | ✕ | ✅ | ✅ | ✕ | paste | sqlite3 + zstd |
| CodeWhale | — | — | ? | ? | ✅ | paste | none |
✅ works · — possible, not built yet · ✕ the harness has no such mechanism · ⚠ blocked by an upstream bug · ? not investigated
Custom store locations go through DEJA_*_ROOT variables, and each agent's own relocation
variable is honored too. The
session format registry documents
the observed paths, record schemas and role mapping per harness, with synthetic fixtures
keeping those descriptions checked against the parsers.
Harnesses with a package of their own
deja install --auto wires every one of these like every other harness, and
that stays the shortest path. They also have a package in their own ecosystem,
for people who install extensions there rather than from a CLI:
| Harness | Package | Install |
|---|---|---|
| opencode | npm opencode-deja | opencode plugin opencode-deja |
| DeepSeek Harness | npm dsh-deja | dsh plugin --profile web add dsh-deja |
| Zed | deja-context-server | Zed → Extensions → deja |
| Kimi Code | plugin deja | /plugins install https://github.com/vshulcz/deja-vu |
| Codex CLI | plugin deja-vu | codex plugin marketplace add https://github.com/vshulcz/deja-vu then codex plugin add deja-vu@deja-vu |
| Grok Build | plugin deja | grok plugin marketplace add xai-org/plugin-marketplace then grok plugin install deja |
| OpenClaw | ClawHub and npm @vshulcz/openclaw-deja | openclaw plugins install clawhub:@vshulcz/openclaw-deja |
| pi (and omp) | npm @vshulcz/pi-deja | pi install npm:@vshulcz/pi-deja |
Either path is enough on its own, and having both is not a problem: every
package reads what deja install wrote first. opencode, dsh and OpenClaw
contribute only what is missing; Kimi, Grok, Codex and pi stand down where the
installer already wired the harness; in Zed both halves use one server id. So
there is nothing to have twice whichever order you install in.
Each uses the deja you already have; the copy it bundles is only the fallback.
The same search is also a skill, for any agent that loads a SKILL.md:
npx skills add https://github.com/vshulcz/deja-vu --skill deja-search   # skills CLI: Claude Code, Cursor, Goose, Copilot…
openclaw skills install @vshulcz/deja-search                            # ClawHub
hermes skills install vshulcz/deja-vu/skills/deja-search                # Hermes
The skill drives the deja binary from the install step above; it does not bundle one.
Semantic recall (optional)
Point deja embed at a local Ollama, LM Studio or OpenAI-compatible endpoint with
DEJA_EMBED_URL and rephrased queries still hit. Without a reachable runtime, lexical
search and MCP recall continue unchanged. OpenAI Platform works with its standard key:
export OPENAI_API_KEY='sk-...'
export DEJA_EMBED_URL='https://api.openai.com/v1/embeddings'
export DEJA_EMBED_MODEL='text-embedding-3-small'
deja embed
With no DEJA_EMBED_URL set, deja probes localhost:11434 and localhost:1234,
so a machine already running Ollama or LM Studio is picked up without being asked.
DEJA_EMBED_OFF=1, or DEJA_EMBED_URL=off, turns that probe off — any other
configured DEJA_EMBED_URL still wins.
For another authenticated OpenAI-compatible endpoint, set DEJA_EMBED_KEY explicitly:
export DEJA_EMBED_URL='https://example.com/v1/embeddings'
export DEJA_EMBED_MODEL='embedding-model'
export DEJA_EMBED_KEY='...'
deja embed
DEJA_EMBED_KEY takes precedence. OPENAI_API_KEY is used automatically only for an
HTTPS api.openai.com URL; it is never implicitly sent to local or third-party endpoints.
Where the vectors live and what they cost
The sidecar sits beside the index as .vectors.bin, not inside index.db. Float32 vectors
cost roughly 4 MB per 1k messages for a 1,024 dimension model. A remote endpoint receives
the redacted indexed text, truncated to about 2k characters, but never raw source files.
With Ollama or LM Studio, embedding stays local and needs no key.
Proof
deja bench recall     # ranking floor: 100 queries, half Russian, CI fails if recall drops
deja bench context    # 30 seeded task chains plus five negative controls
deja bench block      # does the answer survive into what deja hands over
deja bench prompt     # what the per-prompt hook fires on, and what it fires on wrongly
deja bench ingest     # what an update costs: unchanged, a turn, a new transcript, a rename, a rewrite
deja bench read       # what it costs to read a database-backed store, and what one long value does to it
bench block asks the question the other three cannot: with the right session in
hand, does the block carry what that session settled. Eight sessions discuss each
subject and one of them settles it, in the middle of its own transcript rather
than at the end — so the baseline arm, the newest turns of the top hit, scores
zero and an arm above zero had to choose.
| Arm | Carries the answer | Median tokens |
|---|---|---|
deja-block (session-start block) | 1.00 | 665 |
deja-digest (context digest) | 1.00 | 1656 |
newest-turn (baseline) | 0.00 | 289 |
cold | 0.00 | 0 |
The context experiment compares deja-recall against full-history, naive grep and cold context. With the default seed:
| Arm | Median tokens | Median coverage | Negative-control tokens |
|---|---|---|---|
| deja-recall | 1,096 | 1.00 | 0 |
| full-history | 80,547 | 1.00 | 78,145 |
| naive-grep | 273,238 | 1.00 | 0 |
| cold | 0 | 0.00 | 0 |
Same fact coverage as grepping the raw logs for about 250x fewer tokens, and about 70x fewer than replaying the matched sessions in full, while injecting nothing on the chains where no prior fact is relevant. The corpus generator and the relevance labels are ordinary reviewed Go. Audit what "relevant" means before trusting any figure, ours included.
Measured on a real store of 2,419 sessions and 179k messages, 1.9 GB of transcripts:
| Measurement | Result |
|---|---|
| Lookup, in process | 0.7–0.8 ms median (deja bench recall, 100 queries, half of them Russian), ~19 ms on the LongMemEval-S haystacks |
deja <query>, end to end | ~0.2 s median on that store: process start, the freshness check over every store, ranking, printing |
| Freshness check alone | ~50 ms when nothing changed |
| Index size | 200 MB, ~10% of corpus |
The same store has since grown to 2,754 sessions, 358k messages and 5.7 GB. A cold full build over it takes 71 s and writes a 232 MB index — 4% of the corpus, because the share falls as transcripts repeat themselves — and the end-to-end median is unchanged at 0.25 s.
The index is incremental. When a session file grows, only that file is re-read.
How it works
Local inverted index in ~/.cache/deja: parse the JSONL and SQLite stores, redact
credentials, write records.bin plus token buckets, and track per-file state in
manifest.gob so repeat runs only ingest what changed. The MCP server, stats, share and
sync all read that one index. Details in docs/ARCHITECTURE.md.
FAQ
Does anything leave my machine? No, unless you ask it to. See the data flows.
What about secrets already in my logs? They stay in the original harness files, which
are your agent's data; deja secrets names the sessions that carry them so you can rotate
and delete, and --scrub rewrites the transcripts it can reach. Known shapes — AWS keys, api_key=/token= assignments, bearer
tokens and bare JWTs, PEM blocks, provider tokens, high-entropy values — are stripped as
the index is built, so they do not reach digests, shares or sync exports. Pattern matching
is not secret detection: a shape it does not know can pass through. See the
security model.
Will it slow my agent down? A recall is a lexical lookup against a local index: 0.7–0.8 ms median, and nothing waits on a model. A hook adds the process start and a freshness check over your stores on top of that — tens of milliseconds on a store of a few gigabytes.
Do I have to change how I work? No. The agent calls recall itself, and with auto-recall it already knows the project's prior decisions when the session opens.
How is this different from the other memory tools?
| deja | Memory platforms (Mem0, Letta, memU) | Session search (cass) | |
|---|---|---|---|
| Knows work from before you installed it | yes | no | yes |
| Capture step | none, the transcripts are the memory | the agent or your code writes facts | none |
| Needs an LLM or embedding key | no | yes | optional |
| Recalls without being asked | at session start and before a tool runs | no | no |
engram is the strongest of the record-forward tools and worth your time if that model fits you; it still starts empty and knows only what an agent chose to save. The full comparison covers 15 of them.
Where is Claude Code session history stored, and can I search it? Under
~/.claude/projects, one JSONL file per session; Codex keeps ~/.codex/sessions, Cursor a
SQLite state.vscdb. deja search reads them all in place, deja last lists the recent
sessions of every agent, and deja view opens the whole history as one local page. Paths
for each agent: where sessions are stored.
My Claude Code session history disappeared. Is it gone? Claude Code deletes transcripts
older than 30 days (cleanupPeriodDays in ~/.claude/settings.json), and claude --resume lists
only what is left. A session deja indexed before the cleanup stays searchable after the
file is gone. Details: session files on disk.
What about Windows? Builds exist and CI runs the suite there. macOS and Linux are the battle-tested paths. Field reports welcome in #9.
How do I wipe everything?
deja uninstall --all
rm -rf ~/.cache/deja
Guides
Written for the situation rather than the feature:
- Does your agent remember previous conversations? — what each agent keeps between sessions, and what it drops
- Session files on disk — how big
~/.claude/projectsgets, and what deleting it costs - The agent lost the context you had — after a crash, a clear, or a session that came back empty
- The context window is full — what compaction keeps, measured, and what to do instead
- Resuming yesterday's session — find it across every agent, reopen it in the one that owns it
- The agent repeats a mistake you already fixed
- Finding the session where you solved it
- Why agents forget between sessions · Where each agent keeps its history
- What compaction drops · Switching agents · Auditing an agent · Exporting a conversation · Across machines · What memory costs
Per harness: opencode · DeepSeek Harness · Kimi Code · Zed · Grok Build · Gemini CLI · Qwen Code · OpenClaw · Goose · Cline · pi and omp · Hermes
Try it on your own history
curl -fsSL https://raw.githubusercontent.com/vshulcz/deja-vu/main/install.sh | sh
deja install --auto
Ten seconds to install, about ten to index. The next session your agent opens, it already knows what you solved in that project — including everything from before you installed this.
Contributing
make build test lint, then CONTRIBUTING.md. Adding a harness starts in
the parser registry. Priorities and non-goals are in
ROADMAP.md. Good first issues are labeled.
Support
Bugs and questions go to issues. Anything you think is exploitable goes through the private advisory link in SECURITY.md instead. What deja reads, what it never sends anywhere, and how to exclude a project or forget a session is under Privacy.
License
MIT © Vladislav Shulcz